You’re likely to be dealing with more data than your old systems were designed to manage if your business is collecting data from CRM systems, applications, websites, IoT devices, databases and third-party platforms.
That’s where a data lake can come in handy.
You can store both structured, semi-structured, and unstructured data in a data lake without having to pre-define its specific schema before putting it in. This data can then be used for analytics, reporting, machine learning and AI.
However, there’s a key thing to understand before you get started: Constructing a data lake is not the straightforward task of setting up an S3 bucket or cloud storage account, and loading files. Your data lake should be built with a clear architecture, be reliable and ingest data properly, have a strong governance structure, and have continuous data quality controls.
If you’ve been curious about how to build a data lake, then here’s a step-by-step approach.
What Is a Data Lake?
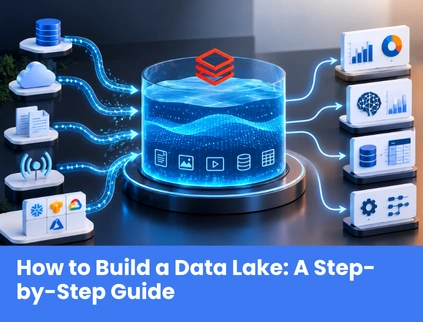
A data lake is a single repository for storing data in its raw or near-raw format. In contrast to a typical data warehouse environment, where the data is typically structured and prepared, a data lake can accommodate a wide variety of data. You might store:
- Structured database records
- JSON and XML files
- Application logs
- IoT and sensor data
- Documents and text
- Images and videos
- Historical datasets
- Streaming data
This flexibility is beneficial if you are not sure how many different ways you want to utilize your data, or it might also be helpful if you aren’t sure how many different data sources you will have in your data lake.
Why Should You Build a Data Lake?
When you’re about to kick off your data lake journey, have a clear understanding of your data lake need. Data lakes are used by businesses frequently to:
- Integrate information from various systems
- Keep huge amounts of data on a large scale
- Help to improve analytics and reporting
- Provide information for machine learning and Artificial Intelligence
- Handle batch and streaming data.
- Reduce data silos
- Preserve raw data to be accessed later on
In the real world, one of the largest advantages is flexibility. Having raw information allows you to transform or analyze it as your new business needs evolve.
Step 1: Define Your Data Lake Requirements
Do not begin with the technology; begin with the business problem. Instead, focus on the purpose of the data lake that you actually want it to serve. Will it be flexible for analytics? Machine learning? Customer insights? AI applications? Real-time processing? Then identify:
- What data you need
- Frequency of the data that will be received
- Overall, who’s going to utilize the data?
- Who will be consuming it.
- What are the security and compliance needs?
From storage to ingestion and governance, these answers have a significant impact on a large number of future choices.
Step 2: Choose Your Cloud Data Lake Storage
The storage layer is the building block of your data lake. Cloud object storage is a modern solution used by most organizations, as they are able to expand without having to continuously add more physical hardware.
Typically, this means Amazon S3, Azure’s Data Lake Storage, or Google Cloud Storage. Assess storage capabilities beyond capacity and look at:
- Cost
- Scalability
- Performance
- Security
- Durability
- Ability to connect to your analytics tools
Pick a storage base that is big enough for your anticipated growth, and not just for what you’ll need now.
Step 3: Design Your Data Lake Architecture
Architect a well-designed data lake to guide your data from ingestion to consumption. A typical method would be to divide the data into logical stages. The raw layer stores data in its original form or in a less processed form. This provides you with a source of information for later reprocessing when needed.
The processed layer is a layer in which data has been cleaned and validated.
The curated layer contains datasets optimized for a designated business, analytics or machine learning use case.
The rules you set up can be different rules or have more layers, but the key is to create clear rules on how data flows around your environment.
Step 4: Connect Your Data Sources
Now, identify the data source(s). Your sources could include:
- CRM and ERP systems
- Relational databases
- SaaS applications
- APIs
- Websites and mobile apps
- IoT devices
- Application logs
- Files and documents
Another thing you need to figure out is how many times a day each source needs to be consumed. For instance, batch processes can be suitable for daily sales data, whereas fraud detection or IoT monitoring might require near real-time streaming.
Step 5: Build Reliable Data Ingestion Pipelines
In the data ingestion layer, data is transferred from source systems into the data lake. That’s where most implementations get tricky. You need to manage failed transfers, duplicates, missing values, schema changes and unexpected changes in source systems in your pipelines.
Some of the options include Apache Spark, Kafka, cloud-native integration services and other data integration tools, depending on your needs. Be sure to not only capture data to storage. Create pipelines that can be monitored, troubleshot, scaled, etc. as data increases.
Step 6: Build Data Quality Into the Process
Even a massive database of information doesn’t necessarily have value. But if there are any duplications, missing values, wrong formats and inconsistencies in data you are providing, your analytics and AI efforts can be affected. Set up checks for:
- Accuracy
- Completeness
- Consistency
- Uniqueness
- Timeliness
- Valid formats
As I have found out, it is a lot easier to identify good quality problems at an early stage rather than seeing them blossom down the line in various downstream systems.
Step 7: Implement Data Governance and Security
Governance is a critical component as you increase the size of your data lake. If left uncontrolled, a data lake can turn into what teams sometimes refer to as a data swamp—a vast body of data from which no one can easily find, comprehend or believe. Your governance plan should identify:
- Data ownership
- Access permissions
- Data classification
- Retention policies
- Data lineage
- Usage monitoring
Identity management and encryption, auditing and proper access control should also be implemented. Where you’re dealing with sensitive or regulated information, security and compliance will be a key part of the architecture.
Step 8: Add Metadata and Data Cataloging
Now you have thousands of datasets, and you have no clue what they are. That’s where metadata and a data catalog come into play. Your catalog should enable users to understand:
- The data that makes up a dataset
- Who owns it
- The meanings of each of the fields
- Where the data was obtained from the PWM warehouse
- The ways it has changed
- Is it of good quality?
- Who can access it
Your data lake is more usable for your engineers, analysts, and data scientists because of good metadata.
Step 9: Connect Analytics, BI, and AI Tools
When your foundation is up, link the tools your teams need. This may be either SQL engines or business intelligence platforms, notebooks, machine learning environments or AI development tools. The purpose is straightforward: to share trusted data with the appropriate people without having to duplicate it all the time.
But modern lakehouse platforms can do more, by integrating data lake storage with analytics that’s more akin to a data warehouse.
Step 10: Monitor and Optimize Your Data Lake
Your data lake doesn’t have to be a one-time thing. Monitor:
- Pipeline performance
- Storage costs
- Data quality
- Processing workloads
- Access patterns
- Failed jobs
It’s also important to have lifecycle policies in place to archive or delete older or unnecessary data. As your business grows your data lake architecture should grow with it.
Final Thoughts
Creating a data lake is the first step, but it’s merely the beginning. The success of a successful implementation hinges on how well these five elements of storage, ingestion, data quality, governance, security, metadata, and analytics are connected.
Building a cloud data lake, whether on AWS, Azure, or Google Cloud, is just part of the equation. Architecture should be based on your business needs.
A data lake can provide your company with a flexible data infrastructure to support data analytics, business intelligence, machine learning, and AI necessary for every new business use case without a lock-in effect.
Looking to compare other options for how to approach modern data architecture, you can check out more data and technology-related resources on Top Data AI Companies.